Models will be wrong.
You can improve the prompt, give them better context, run evaluations, and keep working on the quality of the output. All of that helps.
I still would not design a production system that depends on the model always getting it right.
I learned that pretty concretely building self healing CI.
The system used telemetry and log analytics to identify failures, cluster similar faults, and classify likely causes. A hosted model generated a structured diagnosis and recommended what to do next.
It could get from a failed build to a useful explanation much faster than someone starting with logs and working backward.
Then came the more important decision.
What was it allowed to do about it?
A diagnosis is not permission
The obvious version of self healing is straightforward. Detect the problem, determine the fix, execute it.
I didn't build it that way.
The model could diagnose the failure and recommend an action. It could not decide that its own recommendation was safe enough to run.
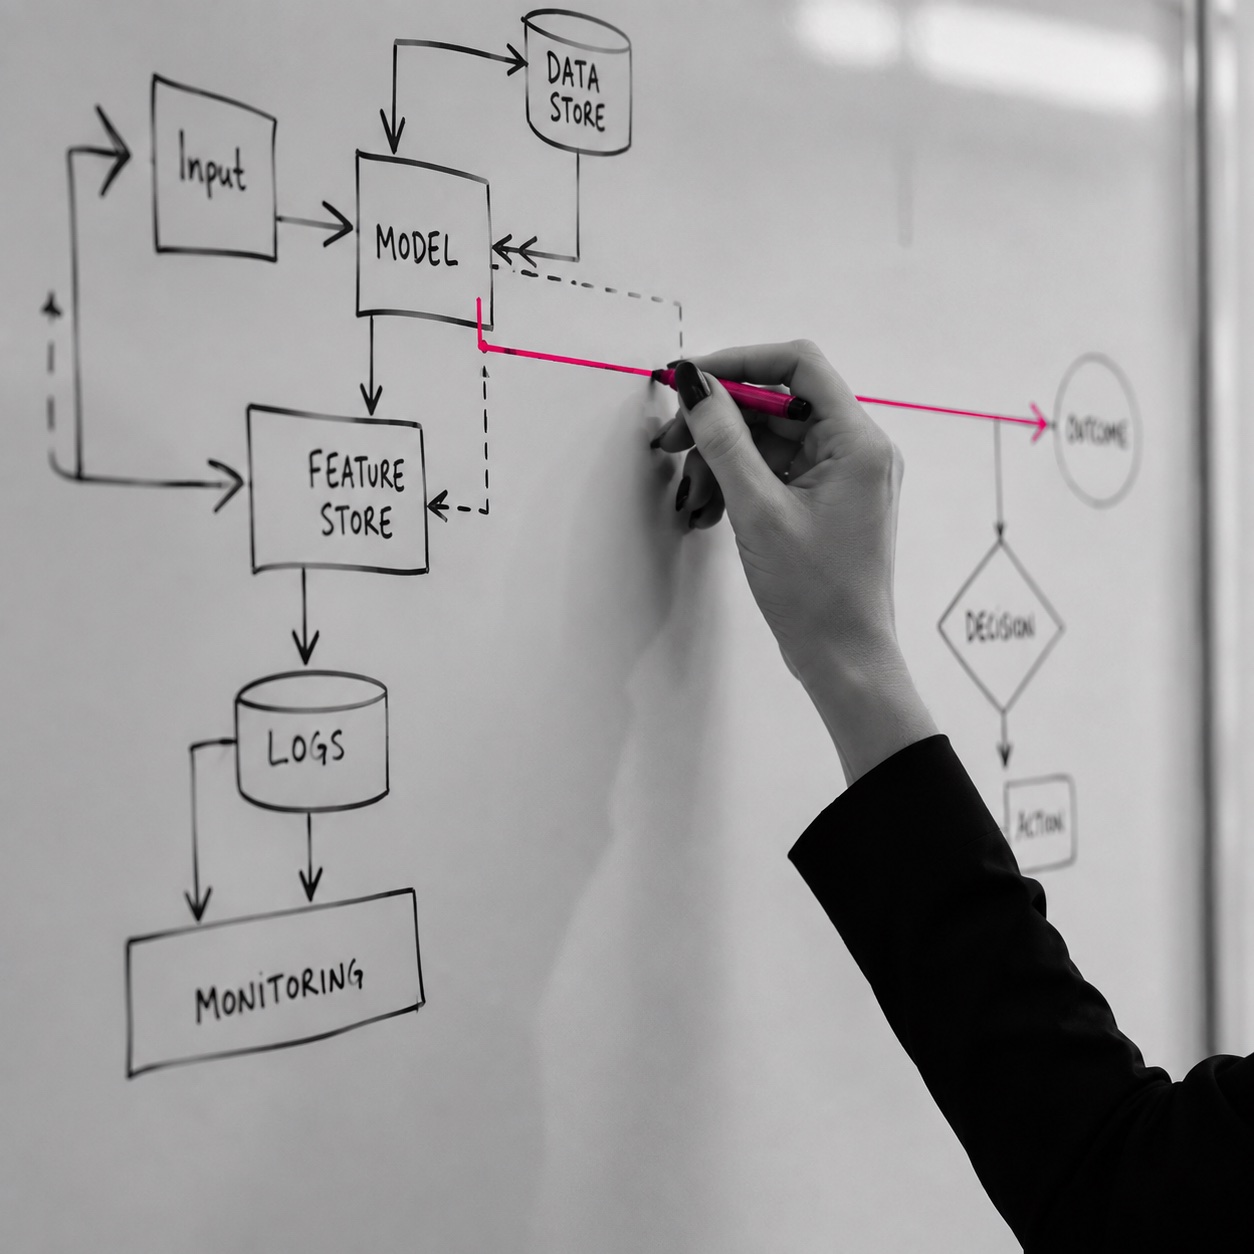
Before anything executed, a controller checked the recommendation against remediation we had already approved. It checked the current state of the system and whether the action could be rolled back. What happened was recorded so we could see what the system had done and why.
If the recommendation didn't clear those checks, it didn't run.
A model is useful here because it can work through a messy failure and still come back with a recommendation. That is not the same thing as giving it the authority to act on that recommendation.
I shouldn't have to read the prompt to figure out what the model is allowed to do. If an agent can restart a service, change production state, approve an exception, or write to a system, I want to be able to see that in the architecture around it. I want to know what it can touch, under what conditions, and how I take that access away.
The prompt can influence what the model recommends. It shouldn't be the thing protecting production.
I was willing to let the model be wrong about what it thought was happening. I was not willing to let being wrong automatically turn into a production change.
That boundary mattered more to me than making the model slightly better at diagnosis.
The boundary moves with the decision
We didn't use the same controls everywhere.
A diagnostic system could cluster recurring failures, flag anomalies, and generate a plain language explanation of what it thought was happening. There was room for uncertainty there because someone could review the diagnosis before acting on it.
A system making a change had much less room. What it could access, what it could change, which actions needed review, what could happen on its own, what got logged, and how you reversed it were decided in the system around the model, not in the wording of the request.
We treated build risk differently too. A build could be scored using information such as code changes, defect history, ownership, test coverage, flaky tests, and production telemetry. What happened next depended on the risk. A build that looked routine did not need the same path as one carrying much more uncertainty.
The consequence of getting those decisions wrong was different, so the controls were different too.
That is also why "put a human in the loop" has never felt like a complete answer to me. A person reviewing every output can make an automated system barely automated at all. Put the person too late and they may only be approving something the system has already effectively decided.
Sometimes a person is the right boundary. Other times it is deterministic code, an approved action, a confidence threshold, or a rollback requirement. How far the model gets before something else has the authority to stop it should be a deliberate decision.
Confidence is information. It isn't authorization.
The failures we already thought of
Those aren't the ones I'm most worried about. They are relatively easy. We can test for them and put controls around them: a recommendation that doesn't match an approved action, a change that can't be rolled back, a service the model was never supposed to touch.
I'm more interested in what happens when the model does something completely plausible that nobody thought to prohibit. You can't write a rule for every bad decision in advance. You can decide how much damage any one decision is capable of doing.
That's why I care about narrow permissions, rollback, and limiting what the model can change far more than trying to make the prompt account for every possibility.
Agreement is not certainty
Another pattern shows up when a team doesn't trust one model's answer: ask another model to check it.
There are places where that is useful. It can give you another signal. It can catch inconsistencies. It can be part of an evaluation system.
I would not use it as the thing standing between a bad answer and a consequential action.
A second model is still a model. It can share the same blind spots, make the same bad inference, or confidently agree with something that is wrong.
If a decision needs to be reproducible, I would rather make that part deterministic.
Routing is a simple example. If a request should go to a particular model based on known things like cost, context length, data sensitivity, or which providers are approved, code can make that decision consistently. There is no reason to introduce uncertainty into it.
The reasoning that happens after the request gets there is different. That may be where a model belongs.
I've worked on systems where models diagnosed failures, generated tests, scored risk, and recommended what to do next. I wasn't trying to remove uncertainty from the model. I was deciding where that uncertainty was acceptable.
The model can make a judgment. The system determines what that judgment is allowed to become.
The model can propose. The system still decides.